Does a Language Model Have to Do All Its Work in Tokens?
Cola2's new checkpoint generates compressed latents before realizing text. Explore its architecture, feedback loop and why fewer training tokens don't establish a from-scratch efficiency gain.
Cola2's new checkpoint generates compressed latents before realizing text. Explore its architecture, feedback loop and why fewer training tokens don't establish a from-scratch efficiency gain.
Sarvam Prism returns decisions without generating text. Its B200 latency, probability fields and calibration tests reveal what engineers need to check before automating a workflow.
FlashProve raises a practical question for hosted AI: can you verify which computation produced an output? A look at commitments, reported proving costs, integer-model limits and the gap between a protocol theorem and deployed software.
Inception's new diffusion language model refines text in parallel. Here's what that changes, how its streaming works, and what early outside tests reveal about speed and reliability.
Meta's new 816B model can run across Macs. But Apple's results show that adding memory and accelerating inference are different jobs—and the way you split the work matters.
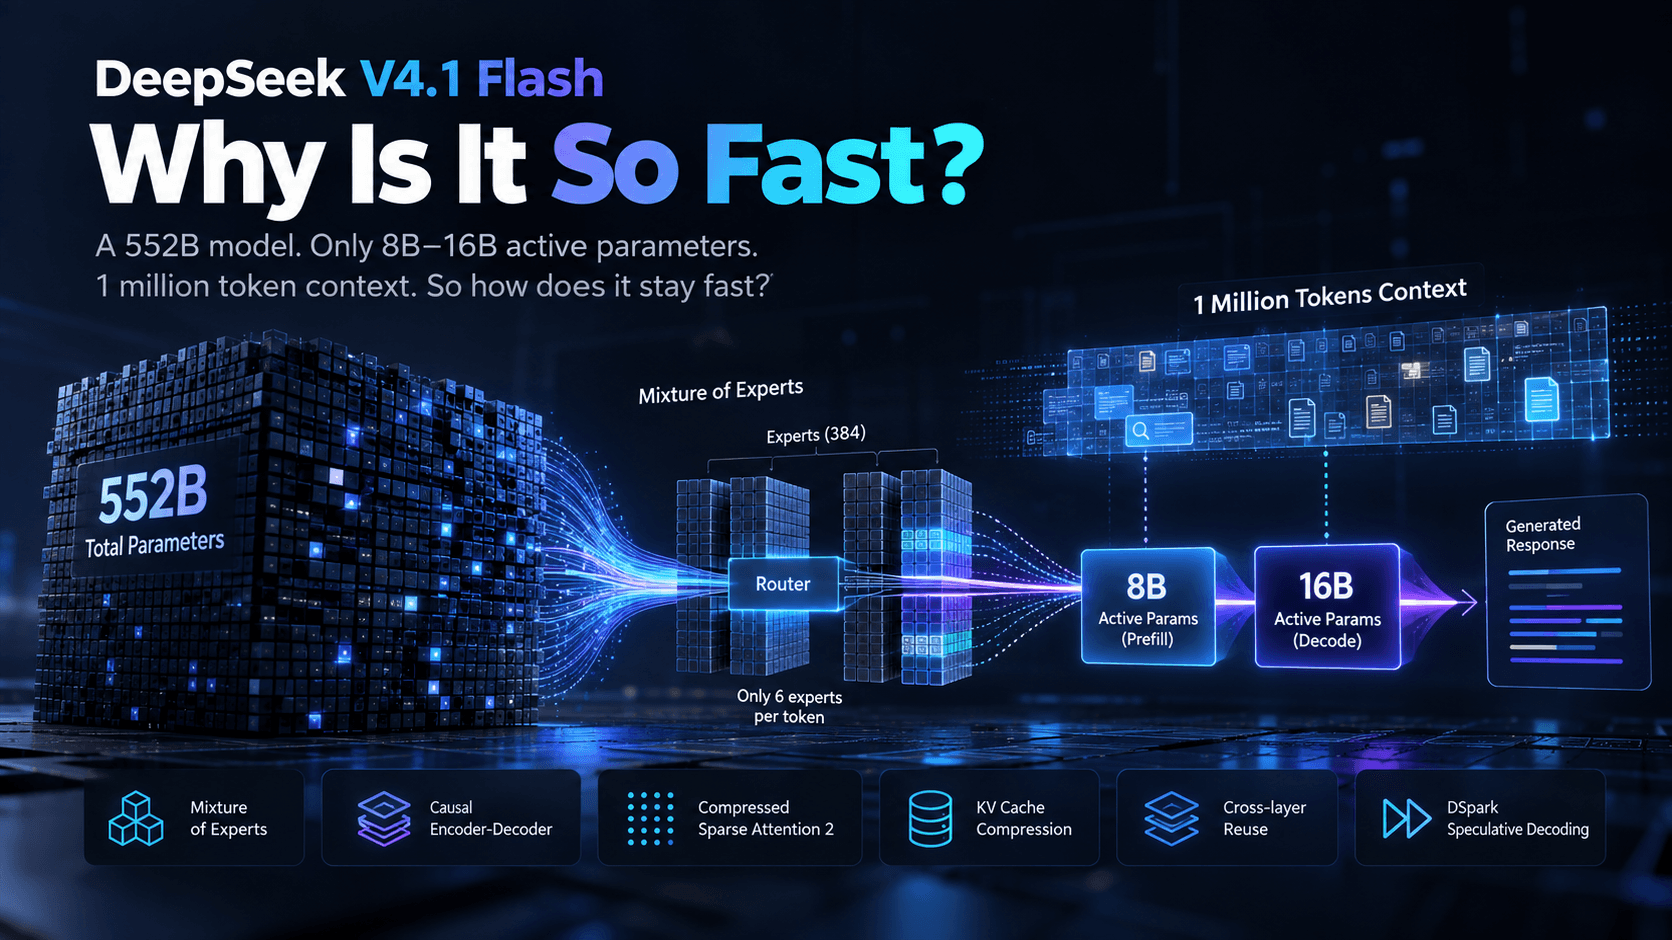
Introduction DeepSeek released DeepSeek V4.1 Flash on September 10, 2026 , describing it as a 552B-parameter Mixture-of-Experts model designed for faster inference, higher throughput, and…