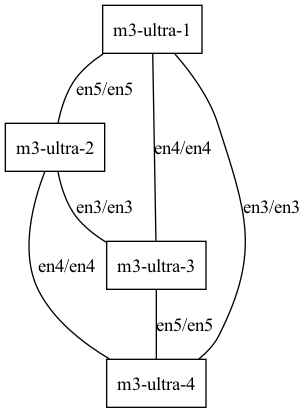
Why Doesn't Adding Another Mac Automatically Make an LLM Faster?
Meta's new 816B model can run across Macs. But Apple's results show that adding memory and accelerating inference are different jobs—and the way you split the work matters.
Meta's new 816B model can run across Macs. But Apple's results show that adding memory and accelerating inference are different jobs—and the way you split the work matters.
CERN and Mistral plan to train a Large Physics Model on simulated collisions. Earlier experiments help explain the promise of transferable scientific models and the tests this new programme still needs to pass.
Liquid AI's LFM2.5-24B-A2B raises a practical question: can a local model handle an agent's full working loop? A look at tool use, reasoning, published benchmarks, memory, and the surrounding application.
Most AI applications today follow a pretty simple pattern: user says something → LLM understands it → LLM decides which tool to call. But do we really need a large language model for that entire…